
NVIDIA L40S, 48 GB
An Ada Lovelace GPU with 48 GB of GDDR6, fourth-generation Tensor Cores with FP8 support and RT cores for rendering.
GPU servers · AI inference
One L40S for inference and media.
$979/mo
Same-day delivery
Excluding taxes · no setup fee · cancel anytime
Overview
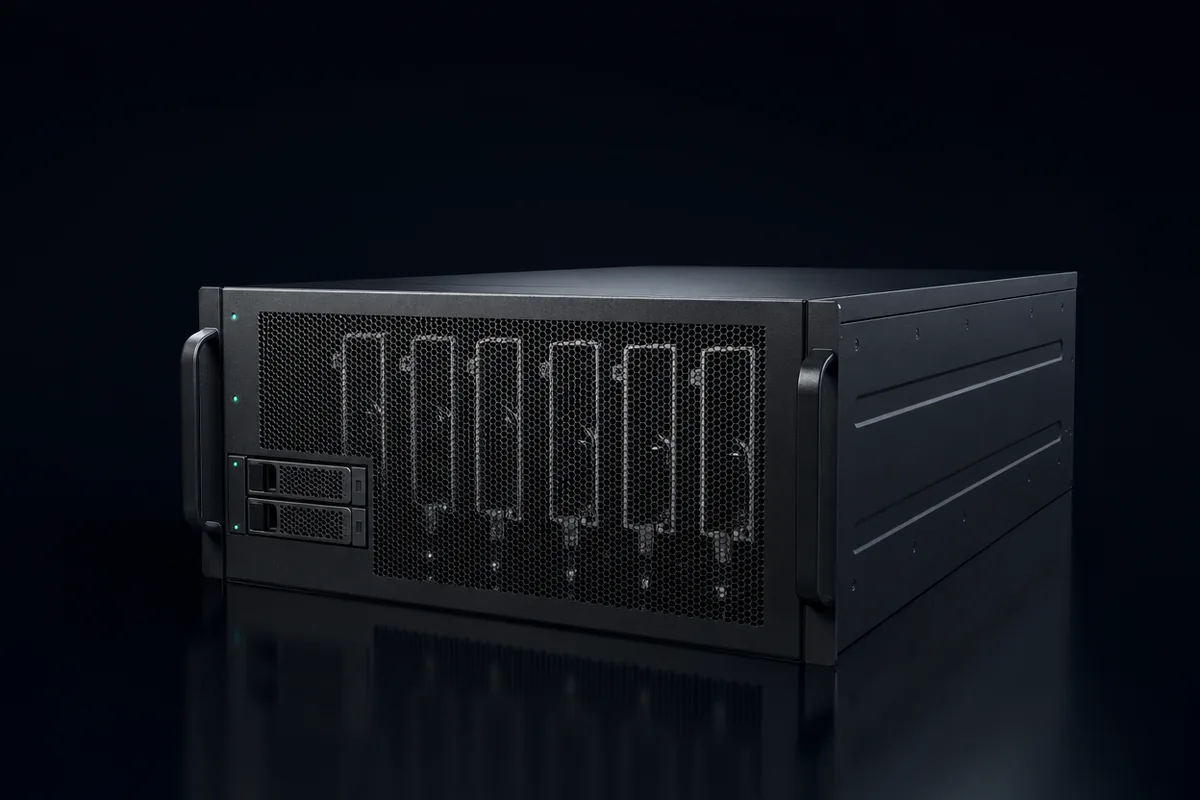
GPU L40S pairs one NVIDIA L40S with 48 GB of GPU memory with a 32-core AMD EPYC 9355P, 256 GB of DDR5-6000 ECC, two 3.84 TB NVMe Gen5 drives and a 25 Gbps port with unmetered traffic. Its sweet spot is serving small and mid-size models, image generation, rendering and video transcoding at a flat $979/mo. It is assembled to order and usually delivered the same day.
Ideal for
An Ada Lovelace GPU with 48 GB of GDDR6, fourth-generation Tensor Cores with FP8 support and RT cores for rendering.
NVENC and NVDEC engines with AV1 support move transcoding onto the GPU, and the 25 Gbps port delivers the output with no egress fees.
64 threads and 256 GB of DDR5-6000 handle tokenization, preprocessing and API serving next to the GPU.
Specifications
| Processor | AMD EPYC 9355PZen 5 · 3.55 / 4.4 GHz |
|---|---|
| Cores / threads | 32 cores / 64 threads |
| GPU | 1 × NVIDIA L40S 48 GBNVIDIA data-center GPU, drivers installable from the OS |
| Memory | 256 GB DDR5-6000 ECC |
| Storage | 2 × 3.84 TB NVMe Gen5 |
| Network port | 25 GbpsUnmetered traffic, inbound and outbound |
| IP addresses | 1 IPv4 + /64 IPv6Additional IPv4 on request |
|---|---|
| DDoS protection | Always on, included |
| Out-of-band access | IPMI and HTML5 KVM console |
| Operating systems | Ubuntu, Debian, AlmaLinux, Rocky Linux, Windows Server, Proxmox VEOr any custom ISO through the KVM console |
| Delivery | Same-day deliveryAssembled to order, usually delivered the same day |
| Billing | $979 per monthNo setup fee, no contract, excluding taxes |
Availability
 New YorkNot offered hereAshburnUS EastDallasUS CentralLos AngelesNot offered here
 AmsterdamNetherlands
 FrankfurtGermany
 LondonNot offered here
 SingaporeNot offered here
 TokyoNot offered here
 SydneyNot offered here
Assembled to order in the available cities and usually delivered the same day. Pick a city to start your order there.
Compare
| Pro seriesPro 32 | GPU servers · this serverGPU L40S | GPU serversGPU RTX PRO | |
|---|---|---|---|
| Price | $749/mo | $979/mo | $2,199/mo |
| Processor | AMD EPYC 9355P | AMD EPYC 9355P | AMD EPYC 9455P |
| Cores / threads | 32 / 64 | 32 / 64 | 48 / 96 |
| GPU | None | 1 × L40S · 48 GB | 2 × RTX PRO 6000 · 96 GB |
| Memory | 384 GB DDR5-6000 ECC | 256 GB DDR5-6000 ECC | 576 GB DDR5-6000 ECC |
| Storage | 2 × 3.84 TB NVMe Gen5 | 2 × 3.84 TB NVMe Gen5 | 2 × 7.68 TB NVMe Gen5 |
| Port | 25 Gbps unmetered | 25 Gbps unmetered | 25 Gbps unmetered |
| Delivery | In minutes | Same day | Same day |
| Locations | 8 | 4 | 3 |
| Action | View Pro 32 | Deploy | View GPU RTX PRO |
FAQ
As an estimate, model weights need about 2 GB per billion parameters at FP16 or BF16 and about 1 GB at FP8. Keeping roughly 8 GB for the KV cache, 48 GB fits models of about 20B parameters at FP16 or about 40B at FP8, and 4-bit quantization fits larger ones. For 70B-class models at FP8 or higher precision, choose GPU RTX PRO.
Yes, within its 48 GB of GPU memory. Parameter-efficient methods such as LoRA and QLoRA make fine-tuning models in the 7B to 13B range practical on a single L40S, depending on sequence length and batch size. Full fine-tuning of larger models needs more GPU memory, such as the 192 GB of GPU RTX PRO.
You choose the operating system and install the NVIDIA driver and CUDA version your stack needs, from NVIDIA's repositories or your distribution's packages; servers are unmanaged, so you keep full control of versions. Ubuntu 24.04 LTS is a common choice for CUDA workloads. For containers, add the NVIDIA Container Toolkit so Docker or Kubernetes can use the GPU.
GPU L40S is available in Ashburn, Dallas, Amsterdam and Frankfurt for $979/mo. It is assembled to order and usually delivered the same day, with no setup fees and no long-term contract.
Usually delivered the same day, with unmetered traffic, DDoS protection and IPMI included.