
GPUAI inference
GPU L40S
- AMD EPYC 9355P32 cores · 64 threads
- 1 × L40S · 48 GBNVIDIA data-center GPU
- 256 GBDDR5-6000 ECC
- 2 × 3.84 TBNVMe Gen5
- 25 Gbps portUnmetered traffic
GPU series · NVIDIA L40S and RTX PRO 6000
Single-tenant servers with NVIDIA data-center GPUs, AMD EPYC 9005 hosts and 25 Gbps ports with unmetered traffic. Run inference, fine-tuning, rendering and transcoding at a flat monthly price, with no hourly GPU billing and no egress fees.
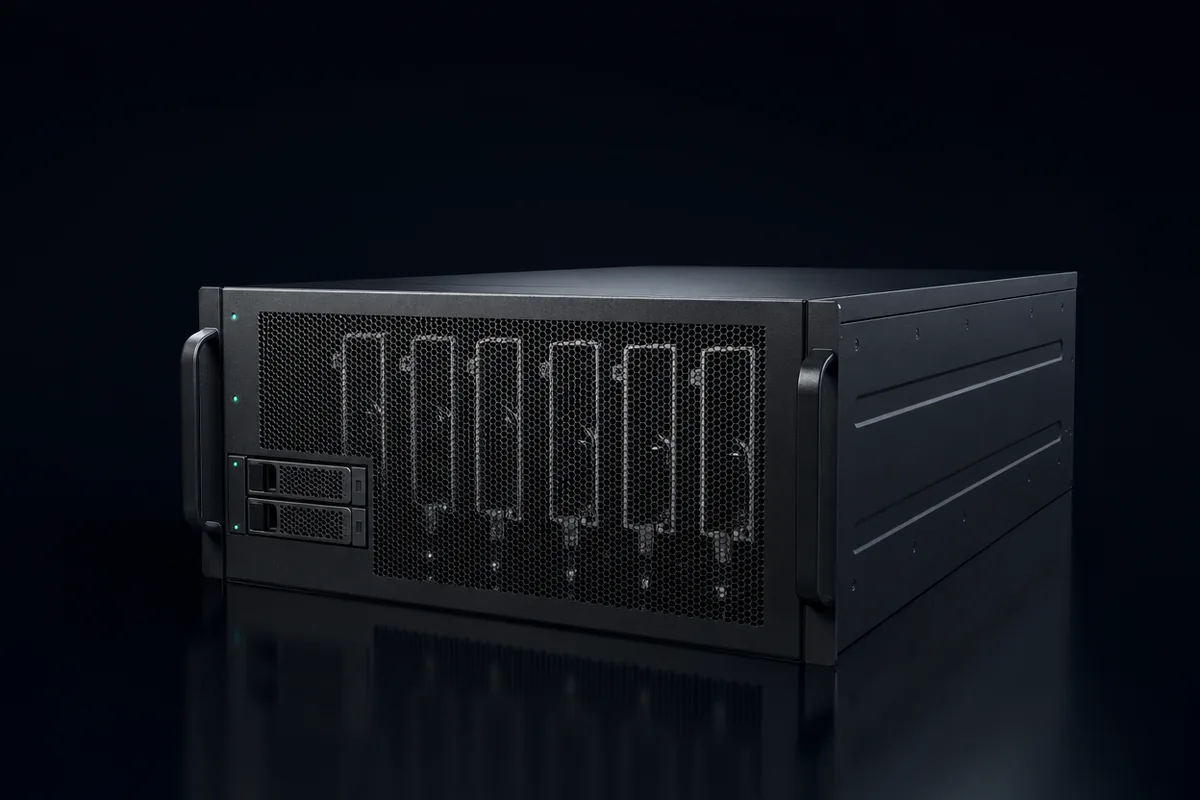
Configurations
Monthly prices in USD, excluding taxes. Unmetered traffic, DDoS protection, IPMI and 24/7 support included.
Why GPU servers
GPU L40S carries one 48 GB L40S; GPU RTX PRO carries two 96 GB RTX PRO 6000 Blackwell cards, for 192 GB of GPU memory.
32 or 48 Zen 5 cores with 256 or 576 GB of DDR5-6000 handle data loading, preprocessing and API serving next to the GPUs.
2 × 3.84 TB or 2 × 7.68 TB of NVMe Gen5 hold model weights, datasets and checkpoints on the same machine as the GPUs.
From $979/mo with unmetered traffic, no setup fees and no long-term contract, so serving more tokens or video does not add egress charges.
Buying guide
The NVIDIA L40S is an Ada Lovelace data-center GPU with 48 GB of GDDR6, fourth-generation Tensor Cores with FP8 support, RT cores and hardware video engines with AV1. The NVIDIA RTX PRO 6000 Blackwell has 96 GB of GDDR7, fifth-generation Tensor Cores with FP4 support and a PCIe 5.0 interface, and can be split into up to four isolated instances with Multi-Instance GPU (MIG).
GPU L40S runs on a 32-core EPYC 9355P with 256 GB of DDR5-6000; GPU RTX PRO runs on a 48-core EPYC 9455P with 576 GB. Both have NVMe Gen5 storage and a 25 Gbps port, are assembled to order and usually delivered the same day. You choose the OS and install the NVIDIA driver and CUDA version your stack needs.
As a sizing estimate, model weights need about 2 GB per billion parameters at FP16 or BF16, 1 GB at FP8 and 0.5 GB at 4-bit, plus memory for the KV cache:
The LLM inference GPU sizing guide explains the method in detail.
Availability
 New YorkNot offered hereAshburn2 configurationsDallas1 configurationLos AngelesNot offered here
 Amsterdam2 configurations
 Frankfurt2 configurations
 LondonNot offered here
 SingaporeNot offered here
 TokyoNot offered here
 SydneyNot offered here
Other families
FAQ
GPU servers are billed monthly at a flat price, $979/mo for GPU L40S and $2,199/mo for GPU RTX PRO, with unmetered traffic and no egress fees. The whole machine is yours around the clock, which suits steady inference and rendering workloads. There is no setup fee or long-term contract, and a cancelled server stays active until the end of the paid period.
As an estimate, weights take about 2 GB per billion parameters at FP16 and 1 GB at FP8, plus room for the KV cache. One 48 GB L40S fits models up to roughly 20B parameters at FP16 or 40B at FP8, while the 192 GB of GPU RTX PRO handles 70B-class models at FP8 on one card or at BF16 across both. Our LLM inference GPU sizing guide covers the method in detail.
Yes. Both GPUs include hardware video encoders and decoders with AV1 support, as well as RT cores for ray-traced rendering. The 25 Gbps port has unmetered traffic, so delivering transcoded video adds no egress fees.
GPU servers are assembled to order and usually delivered the same day. GPU L40S is available in Ashburn, Dallas, Amsterdam and Frankfurt, and GPU RTX PRO in Ashburn, Amsterdam and Frankfurt. Other GPU counts and fleets are available as custom builds by quote.
From $979/mo with unmetered traffic, DDoS protection and IPMI included. No setup fees, cancel anytime.